 Products




Ready to get started?
No matter where you are on your CMS journey, we're here to help. Want more info or to see Glide Publishing Platform in action? We got you.
Book a demoPersonalization based on guesswork and inferred patterns has reduced in effectiveness compared to targeted personalization from declared data and real signals shared by people: "zero-party data". Glide Nexa stores every follow, save, and preference against a known profile, increasing your ability to target content and offers effectively.
Personalizing content and information has always been a key task of a content or marketing team, well before digital media and recommendation engines existed. Editors would choose what stories to lead a page or section, using gut feel and sales figures to make judgment calls, while marketing teams used things like demographic data and response data to estimate what would work best where. Over time, even without knowing a single reader's name, good editors and marketing teams built up a feel for what would work based on the aggregate of what they could see or measure.
Digital media sent that into overdrive, allowing site owners to track patterns and journeys and build a compelling picture of what people liked based on inferences alone. Clicks, device types, and dwell time started to usurp individual judgment, and cumulatively a new set of rules dominated, but still without knowing who the reader is or what they actually like.
But both models have something missing: actual insight from real people on what they do and do not like. And because of that reliance on educated guesswork, the value of the inferred data is far lower, both in terms of making confident decisions about content and campaigns, and from a commercial standpoint too.
As search and recommendation algorithms on the distribution side advance in leaps and bounds, the power of inferred preferences on the publishing and media side has diminished in value and effect. It’s a scenario being made worse by rapidly changing regulations around tracking and what information a cookie can store.
There is a simpler model. Ask them. Ask readers what they care about, remember what they tell you, and use that to shape their experience. Preference-based personalization starts with declared data, signals the reader actively provides, rather than signals extracted from their behavior without their awareness.
The industry now has a name for data a reader shares deliberately: zero-party data. It sits alongside first-party data (behavior you observe on your own platform), second-party data (another organization's first-party data, shared directly), and third-party data (bought from outside sources). Declared data and zero-party data describe the same thing: information the reader hands over on purpose. The difference in origin is what makes it more reliable than anything you infer.
Inferred data comes from observing behavior and drawing conclusions. A reader visits three baseball articles, so the system infers they like baseball. They spend four minutes on a long-form analysis piece, so the system infers they prefer in-depth content. They visit at 7am on weekdays, so the system infers they are a morning reader.
Each inference is a probability, not a fact. The reader might have clicked those sports articles because they were on the homepage, not because sports is their primary interest. The four-minute session might have been an idle tab. The morning visits might be a temporary pattern during a commute that changed last week.
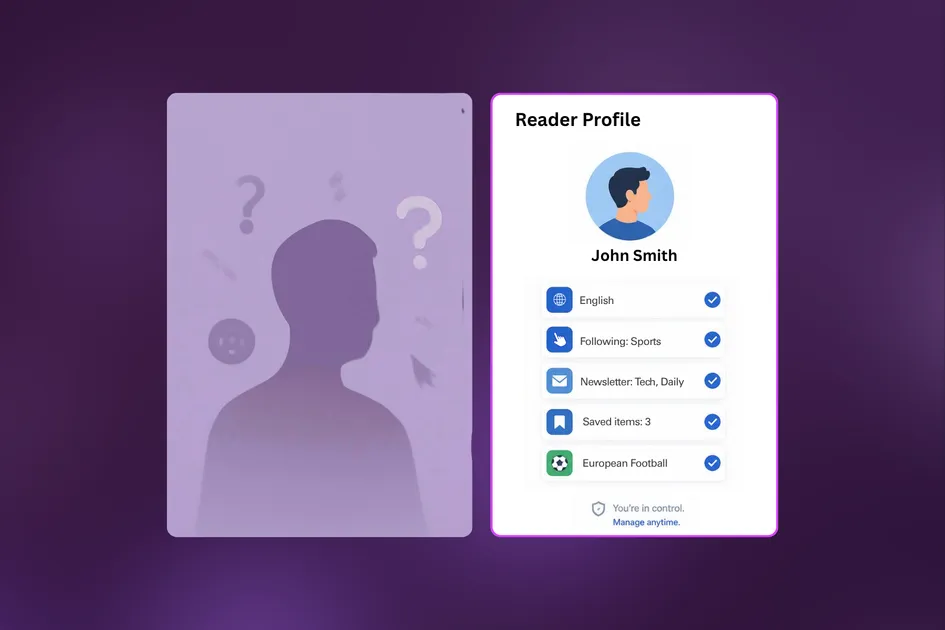
Declared data is more useful because it comes from the reader directly, giving genuine signals about what they like:
These are statements of intent from the reader, not guesses. Following a topic says "I want more of this", saving an article says "this has lasting value to me", and picking a newsletter chooses a relationship with a specific content area.
The mechanics are deliberately light. A reader taps follow on an author's page, and their next visit surfaces more of that author's work. They pick the technology newsletter at sign-up, and that is the edition they receive. Each action is a single tap that pays the reader back immediately, which is what keeps them declaring more over time.
The practical machinery of inferred personalization depends on persistent tracking. You need to recognize the same person across sessions, accumulate their behavior into a profile, and feed the profile into a recommendation engine.
Third-party cookies made this relatively straightforward for years. They are now disappearing, and browser privacy features are becoming more restrictive. Platform policies limit cross-site tracking. GDPR and similar regulations require explicit consent for the kind of tracking that inference relies on, and consent rates for tracking are consistently low.
Inferred personalization systems now work with less data, shorter histories, and more fragmented signals than they were designed for. Recommendations get worse and the gap between what readers want and what the system guesses widens.
Meanwhile, declared data has none of these dependencies. A reader who follows a topic does not need a cookie for that preference to persist. It is stored against their authenticated profile and remains valid until they change it. No browser policy, platform decision, or regulatory change can erode it.
In Glide Nexa, declared data accumulates through a reader's normal interactions with a site. Each interaction is recorded with its type, intent, timestamp, and the content item it relates to. The key sources are:
Declared preferences become useful when they feed back into the reader's experience.
A reader who follows three topics and two authors has told you precisely what their ideal homepage looks like. Content matching those follows can be prioritized in feeds, section pages, or personalized recommendation modules. The confidence level is high because the reader explicitly chose those preferences.
Newsletter editions, push notifications, and email campaigns can be targeted on declared interests rather than inferred segments. A reader who selected the "Technology" newsletter and follows the "AI" topic receives the AI-specific newsletter edition. No inference required, no risk of irrelevance.
Nexa's poll targeting connects directly to declared data. A poll about premium content satisfaction appears only to users with active premium subscriptions. A sponsor-branded prediction poll targets users in a specific geographic region who follow a particular sport. The targeting rules reference what Nexa already knows from declared preferences, entitlements, and group memberships, and combine them with AND logic.
On the commercial side, advertisers value declared data because it is specific, consented, and verifiable. A segment such as "declared Premier League football fans who engage with prediction content weekly" is built entirely from declared behavior. It does not rely on probabilistic modelling or cookie-based inference, which means it survives every privacy change intact.
The most common mistake is asking for too much, too soon. A long sign-up form demanding age, location, job title, and interests before a reader has seen any value kills conversion. Declared data works best when it is collected gradually, at moments where stating a preference clearly benefits the reader.
Topic and author follows are the easiest starting point. A "follow" button on an article or author page asks for nothing except a tap, and the payoff is obvious: more of what the reader just chose. Newsletter selection is a close second, because the reader is already opting into a relationship and choosing a subject area is a natural part of that.
From there, preferences can deepen over time. A reader who follows three topics might later set a content language, mute a subject they are tired of, or answer a one-question poll about what they want to see more of. Each step is small and optional, tied to a clear benefit. The profile builds itself through use rather than through a single demanding form.
The principle is a fair value exchange. Every time you ask a reader to declare something, they should get something back: a better feed, a relevant newsletter, a saved reading list they can return to. When the exchange is fair, readers keep declaring, and the profile keeps improving.
This is not an argument for abandoning behavioral signals. Reading frequency, session depth, and content consumption patterns remain useful context, and what people say they like and what their patterns suggest they like are not always the same. Inference also drives discovery: it can surface something inferred data heavily suggests a reader would enjoy but has not thought to follow, which declared data alone can never do. But declared data should be the foundation, supplemented by inferred signals, not the other way around.
When both are tied to the same authenticated profile, as they are in Nexa, the picture becomes precise. You know a reader follows "Technology" (declared), reads an average of four tech articles per week (observed), saved three pieces about AI regulation this month (declared), and visits most often between 7am and 9am (observed). Each layer adds confidence to the other.
The difference is what happens when part of the signal disappears. If browser changes break session tracking, the declared preferences remain. If a reader clears their history or uses a different browser, their follows, saves, and newsletter selections are still intact in their Nexa profile. Declared data is resilient in a way that inferred data is not.
Declared data also has a better legal basis. A reader who actively follows a topic is providing information voluntarily, stored on your own platform and used with their explicit awareness. There is no ambiguity about consent and no risk that a regulatory change invalidates how you collected it. For teams operating under GDPR or similar frameworks, that is really important.
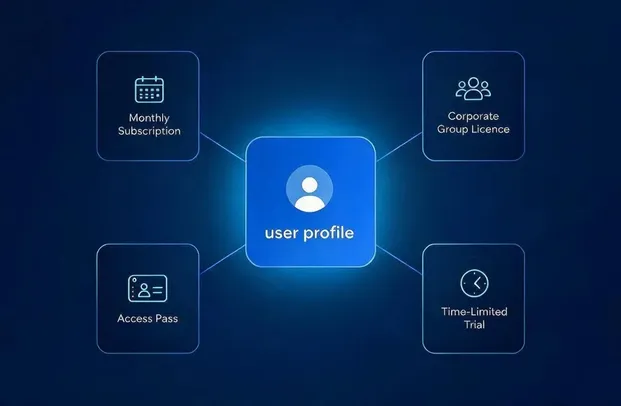
Glide Nexa stores all declared data against a single authenticated user profile. Every follow, save, poll response, newsletter selection, and custom field value builds up with every interaction into a profile that improves over time.
The platform captures each interaction in real time, with its type, intent, timestamp, and the content item it relates to. Engagement analytics are generated automatically: weekly and monthly snapshots, breakdowns by interaction type, time-of-day patterns, and per-user activity summaries.
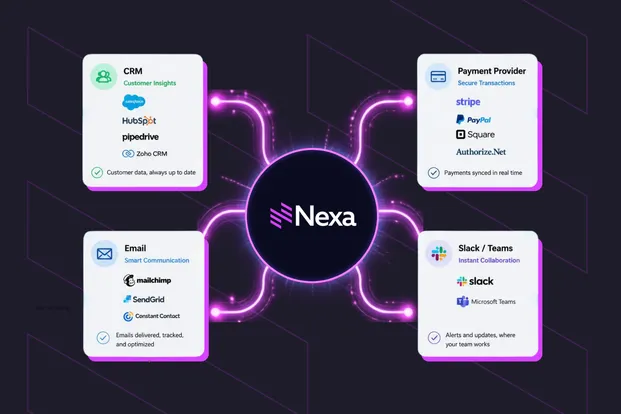
Because Nexa is the identity hub connecting newsletters, commenting, polls, and subscription services, the declared data from every touchpoint flows into the same profile. Email platforms pull identity and preferences from Nexa. Commenting systems tie posts to known users, poll participation logs against real people, and you get a consolidated picture rather than fragmented preferences scattered across separate systems.
For organizations already using Glide CMS, Nexa integrates natively. For those on other platforms, Nexa deploys standalone and connects via API. The declared data it collects is first-party, fully owned by you, and available to any connected system through REST APIs or structured data exports.
Personalization built on what readers tell you, rather than what you guess about them, is more accurate and longer-lasting. It also puts less load on your own systems than a recommendation engine trained on behavioral inference, because the reader does most of the work by telling you what they want.
To explore how Glide Nexa can support preference-based personalization and zero-party data for your audience, connect with a Glide product specialist.
Common questions
What is the difference between declared data and zero-party data? They describe the same thing. Zero-party data is the term that has become common in marketing and martech, while declared data is the plainer description. Both mean information a reader shares intentionally, such as a followed topic or a newsletter choice, rather than data inferred from behavior.
Is declared data the same as first-party data? Not quite. First-party data usually refers to behavior you observe on your own platform, such as which articles a reader opens. Declared data is what the reader says directly. Both are collected on your own platform and owned by you, but declared data carries clearer intent and a cleaner consent basis.
Does preference-based personalization replace behavioral tracking? No. Behavioral signals still add useful context. The point is to make declared data the foundation and let behavioral signals supplement it, rather than building personalization on inference alone.
How do readers declare their preferences? Through normal interactions: following topics and authors, saving articles, choosing newsletters, voting in polls, setting a content language, or setting a preference. Each action is a deliberate signal, stored against the reader's profile.
What happens to declared preferences when cookies disappear? Nothing. Declared preferences are stored against an authenticated profile, not a browser cookie. They persist through browser changes, cleared histories, and device switches, which is what makes them more durable than inferred signals.
Related articles:
No matter where you are on your CMS journey, we're here to help. Want more info or to see Glide Publishing Platform in action? We got you.
Book a demo
